Optimized Models for Every Industry

Pre-trained models engineered for diverse AI applications and optimized for peak performance on our silicon
Select Chip(s)
Select AI Model Provider
Browse our model collection and view performance benchmarks. Sign up to access advanced features.
Computer Vision

ConvMixer-768_32

Image Classification

Combines large-kernel depthwise convolutions for spatial mixing with pointwise convolutions for channel mixing in a simple, MLP-style block.

Useful for research, ablation studies, and lightweight models, offering transformer-like performance with very few architectural components.
Computer Vision

ConvNeXt-Tiny

Image Classification

Modernized CNN incorporating transformer-era design cues like large kernels, fewer activations, and simplified blocks.

Performs well in high-resolution tasks (detection/segmentation) while retaining convolutional efficiency, making it great for real-time industrial vision.
Computer Vision

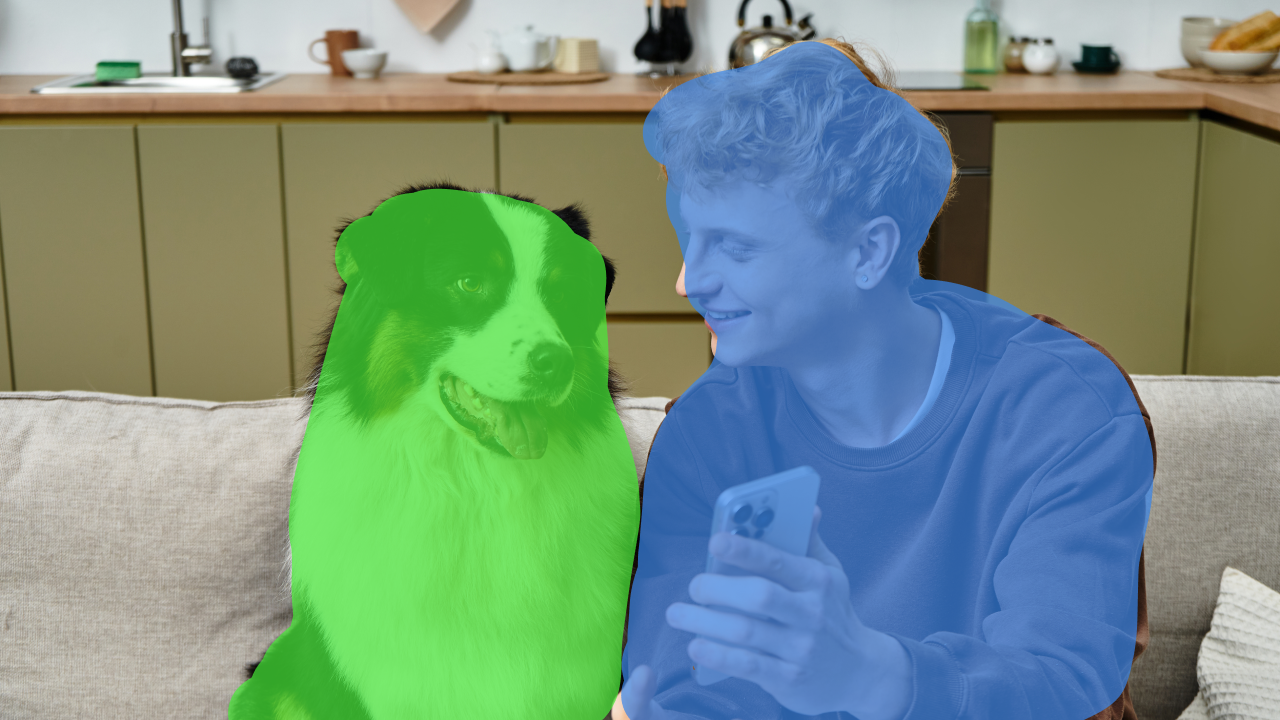
DeepLabV3Plus-ResNet50

Semantic Segmentation

DeepLabv3+ uses an encoder-decoder architecture with atrous spatial pyramid pooling (ASPP) to capture multi-scale context and refine object boundaries for precise segmentation.

Widely used in autonomous driving, medical imaging, and satellite imagery where accurate pixel-level class labels are critical.
Generative AI

Deepseek-R1-Distill-Qwen-1.5B

Language Model

A 1.5B-parameter distilled reasoning language model derived from DeepSeek-R1 and based on the Qwen architecture, optimized to preserve effective reasoning and instruction-following capabilities while significantly reducing compute and memory requirements.

Suitable for resource-constrained on-device and edge AI assistants, lightweight coding and technical Q&A, structured reasoning tasks, and conversational applications requiring low latency and efficient deployment.
Generative AI

DeepSeek-R1-Distill-Qwen-7B
Language Model
A 7B-parameter distilled reasoning language model derived from DeepSeek-R1 and based on the Qwen architecture, optimized to retain strong chain-of-thought reasoning and instruction-following capability with reduced compute cost.
Suitable for efficient on-device or edge AI assistants, coding and technical Q&A, structured reasoning tasks, and enterprise chat applications requiring strong reasoning with moderate hardware resources.
Computer Vision

DepthAnythingV2-Small

Depth Estimation

DepthAnythingV2 uses a transformer-based encoder-decoder architecture with multi-scale feature fusion to generate high-resolution, accurate depth maps from monocular or multi-view RGB inputs.

Applied in robotics, AR/VR, autonomous navigation, and 3D scene reconstruction where precise spatial understanding of the environment is required.
Computer Vision

DWPose-t

Pose Estimation

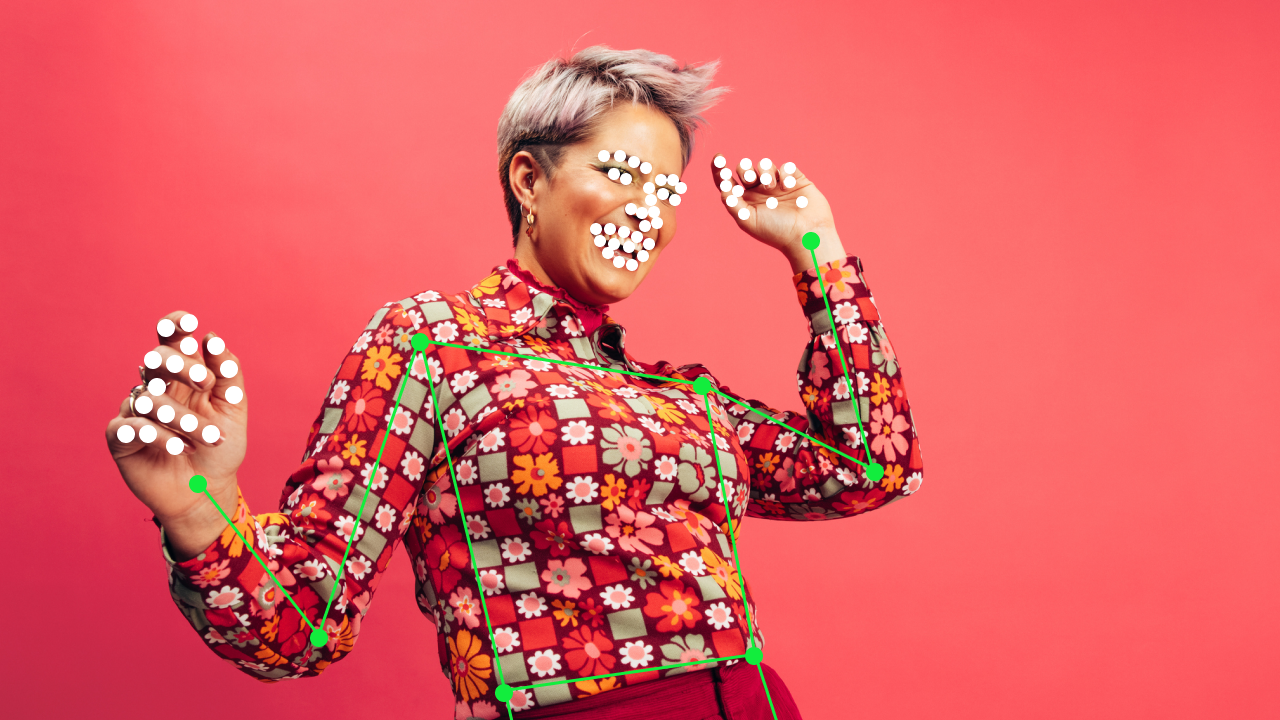
DWPose is a lightweight, high-performance whole-body pose estimation model that predicts human body, hand, and facial keypoints for detailed pose representation.
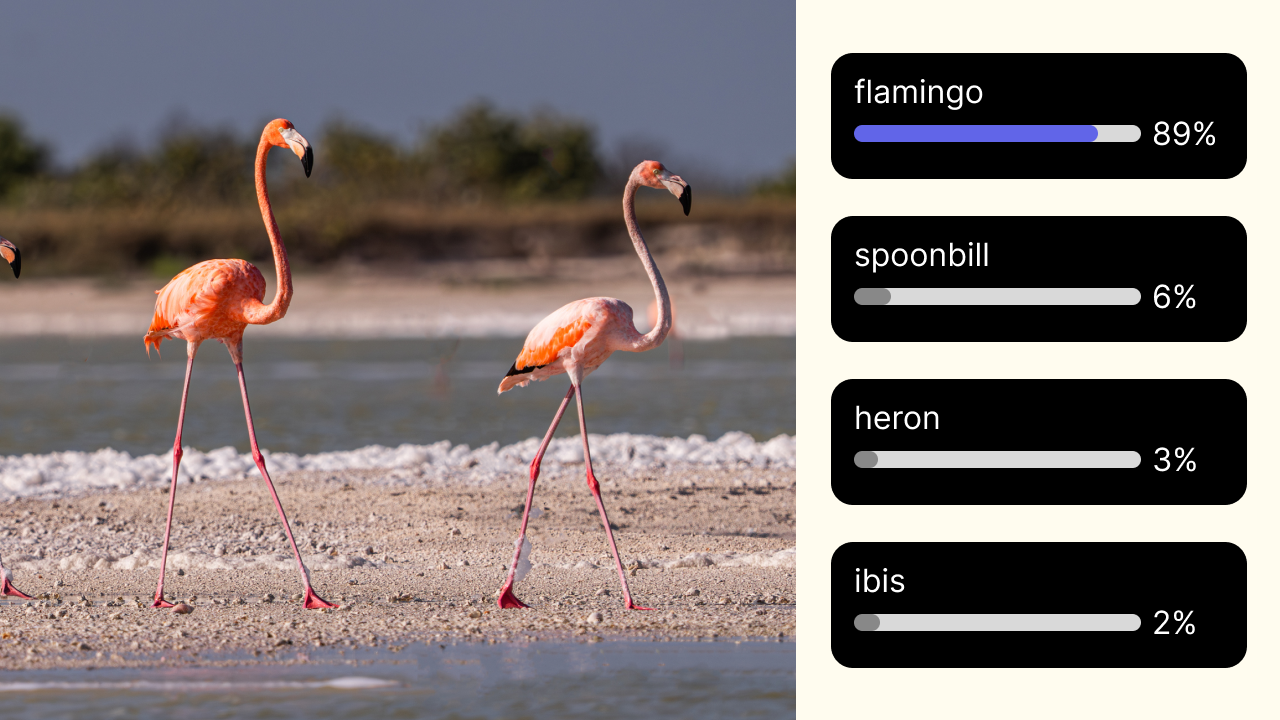
Well suited for human motion analysis, gesture recognition, virtual avatars, animation, and video generation applications requiring detailed whole-body pose information.
Computer Vision

EfficientNet-Lite0

Image Classification
EfficientNet-Lite is a mobile-optimized CNN family derived from EfficientNet, using efficient MBConv blocks and a streamlined architecture to reduce latency, memory, and computational requirements on edge hardware.
Well suited for on-device image classification in applications such as smart cameras, mobile devices, IoT vision, and embedded systems where low power and real-time inference are important.
Computer Vision

EfficientNetV2-S

Image Classification

Uses compound scaling and fused-MBConv blocks to achieve fast training and high accuracy across image resolutions.

Suited for production-scale cloud deployments where both accuracy and training speed matter (e.g., large-dataset classification).
Computer Vision

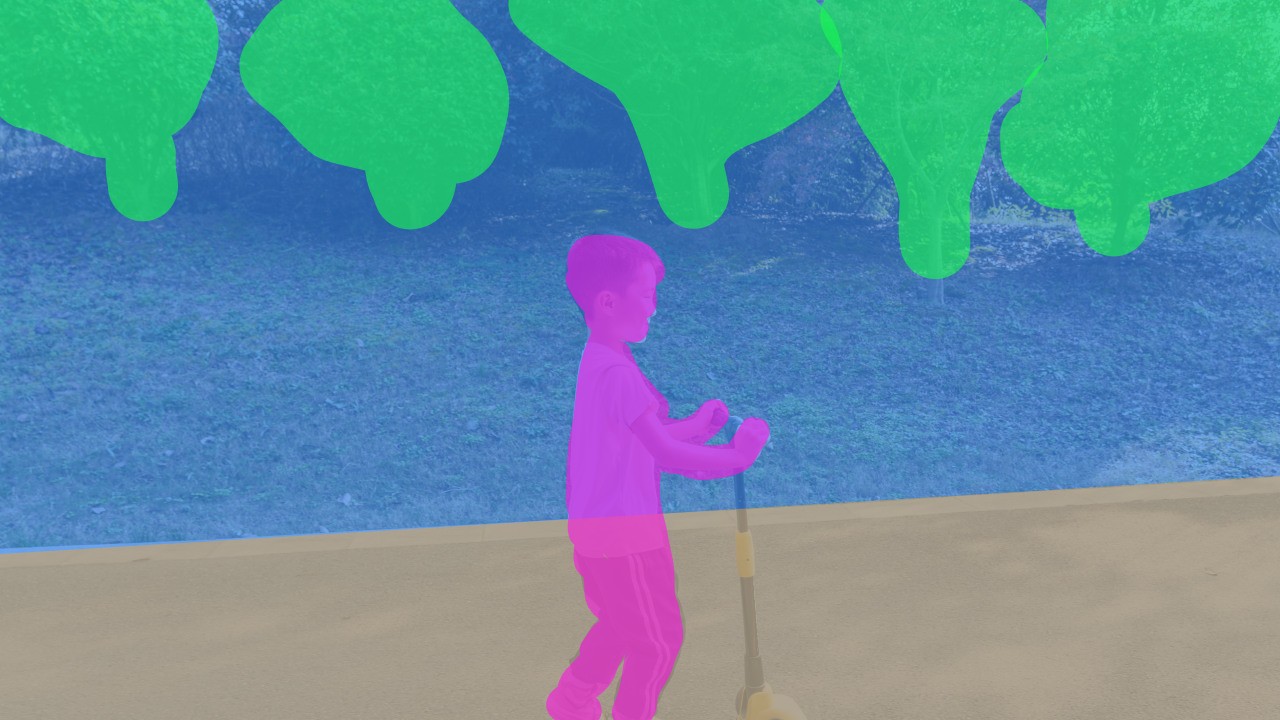
EfficientViT-L2

Image Classification

Designed for efficient vision transformers using linear attention, structured pruning, and hardware-friendly operator choices.

Great for edge AI deployments that want transformer accuracy with mobile-level latency—e.g., drones, AR glasses, and security cameras.
Computer Vision

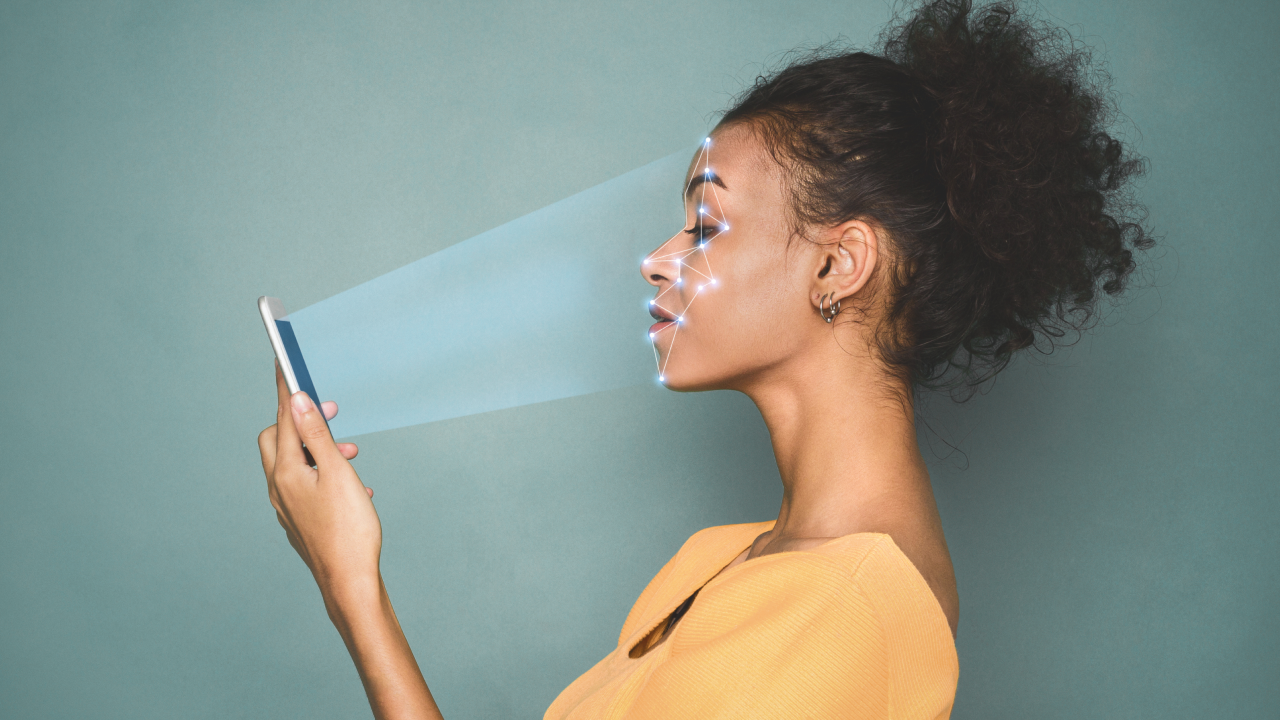
Facenet-MobilenetV1

Face Recognition & Face Detection

FaceNet-Mobilenet combines a lightweight MobileNet backbone with a triplet-loss-trained embedding network to generate compact, discriminative facial feature vectors for identity verification.

Used for mobile and edge authentication, smartphone unlock, attendance tracking, and verification systems where low-latency, on-device recognition is critical.
Generative AI

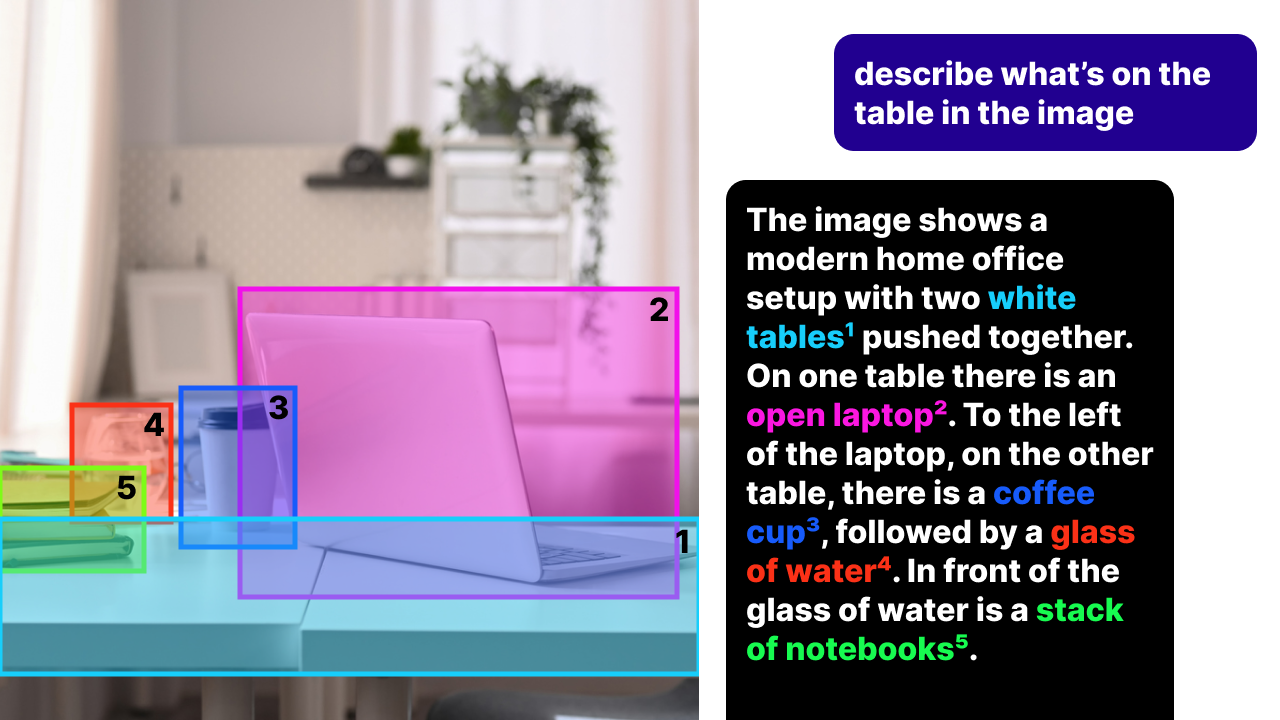
Florence-2-base
Vision-Language
Florence-2-base is a lightweight vision-language model that uses a unified Transformer architecture to perform multiple vision tasks—including image captioning, object detection, visual grounding, and segmentation—through task-specific prompts.
Well suited for edge vision applications requiring multiple capabilities from a single model, such as image captioning, visual search, object localization, and image-based content understanding.
Computer Vision

FSRCNN x4

Super-Resolution
FSRCNNx4 is a lightweight convolutional super-resolution network that reconstructs a high-resolution image from a low-resolution input using efficient feature extraction, nonlinear mapping, and deconvolution layers with 4× upscaling.
Well suited for edge applications such as camera/image enhancement, video upscaling, surveillance, and improving the resolution of low-resolution sensor imagery where low latency and compute efficiency are important.
Generative AI

InternVL3.5-1B

Vision-Language

A lightweight multimodal vision-language model (~1B parameters) combining a compact vision encoder with a language model through multimodal alignment training for efficient image-text understanding and generation.
Suitable for edge AI use cases such as visual question answering, document/image understanding, smart surveillance analytics, and multimodal assistant applications.
Generative AI

InternVL3.5-20B-A4B

Vision-Language
A multimodal mixture-of-experts model combining the InternViT-300M vision encoder with the GPT-OSS-20B-A4B language model, using InternVL3.5’s multimodal alignment and Cascade RL training for strong visual reasoning with only a subset of language-model parameters active per inference.
Suited for compute-intensive edge or server applications requiring advanced multimodal reasoning, such as document and chart analysis, visual Q&A, complex image understanding, and agentic/GUI interaction.
Generative AI

InternVL3.5-2B

Vision-Language
A mid-scale vision-language model (~2B parameters) that integrates a stronger vision encoder with a larger language model to improve multimodal reasoning, visual grounding, and generation quality.

Well suited for higher-accuracy multimodal assistants, document and scene understanding, advanced visual Q&A, and analytics workloads where improved reasoning is needed without moving to very large VLMs.
Generative AI

InternVL3.5-4B

Vision-Language
A larger multimodal vision-language model (~4B parameters) combining a high-capacity vision encoder with a stronger language backbone to deliver improved multimodal reasoning, detailed visual understanding, and more coherent text generation.

Suited for advanced multimodal assistants, complex visual question answering, document and scene analysis, and higher-accuracy edge or server deployments requiring richer image-text reasoning.
Generative AI

LFM2.5-VL-1.6B

Vision-Language
A 1.6B-parameter vision-language model from Liquid AI, offering a larger multimodal reasoning capacity than the 450M variant while retaining an architecture optimized for efficient inference and deployment on resource-constrained hardware.
Well suited for edge applications requiring stronger visual understanding, such as visual question answering, document/OCR analysis, image captioning, and multimodal assistants where a balance of accuracy and efficiency is important.
Generative AI

LFM2.5-VL-450M

Vision-Language
A compact 450M-parameter vision-language model from Liquid AI, designed for efficient multimodal understanding with a lightweight vision encoder and language model optimized for low-latency, resource-constrained inference.
Well suited for edge applications such as visual question answering, image understanding, OCR/document analysis, and lightweight visual assistants where memory and latency are critical.
Generative AI

LLaVA-OneVision-Qwen2-7B

Vision-Language

LLaVA OneVision integrates a large language model with a visual encoder to perform multimodal reasoning, allowing the model to generate text outputs conditioned on visual input.

Suitable for visual question answering, interactive AI assistants, and reasoning over diagrams or documents combining image and text information
Computer Vision

LongCLIP-B16

Image Classification

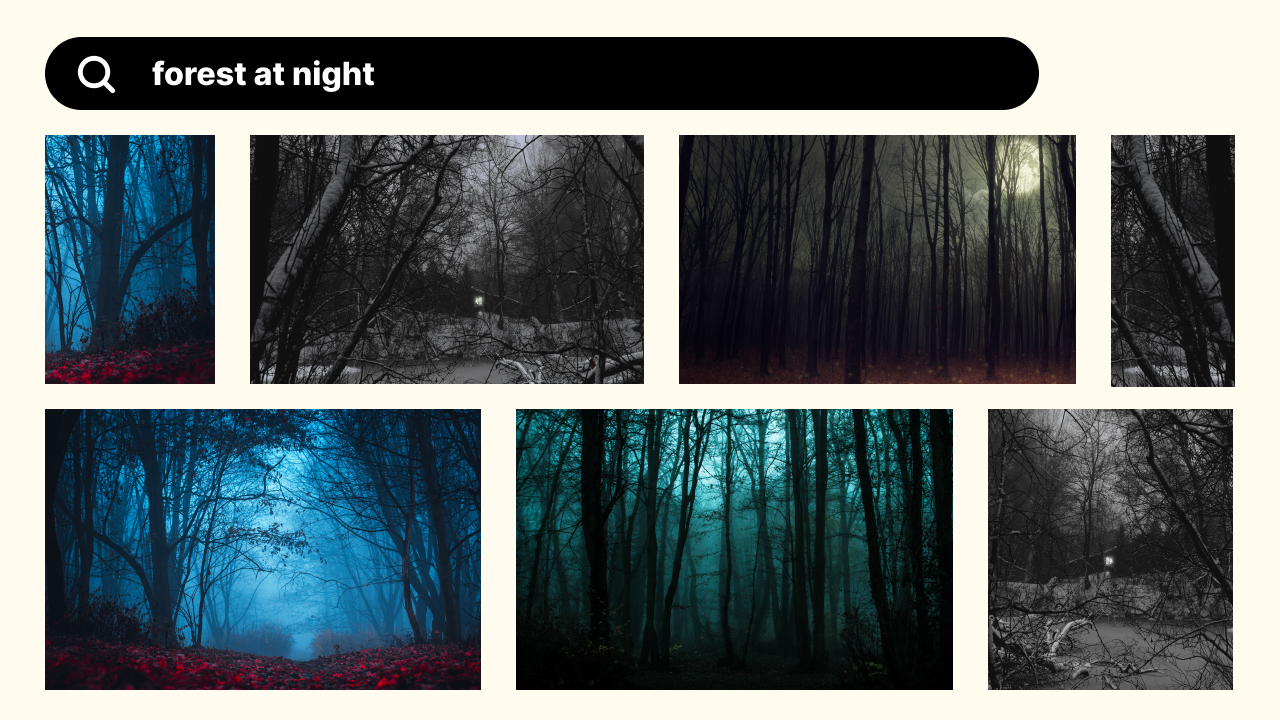
LongCLIP extends CLIP with a memory-efficient architecture to handle high-resolution and long-sequence images, enabling robust image-text alignment over larger visual contexts.

Useful for zero-shot large-scale image retrieval, document understanding, and multimedia search where high-resolution image-text matching is needed.
Computer Vision

MobileNetV2

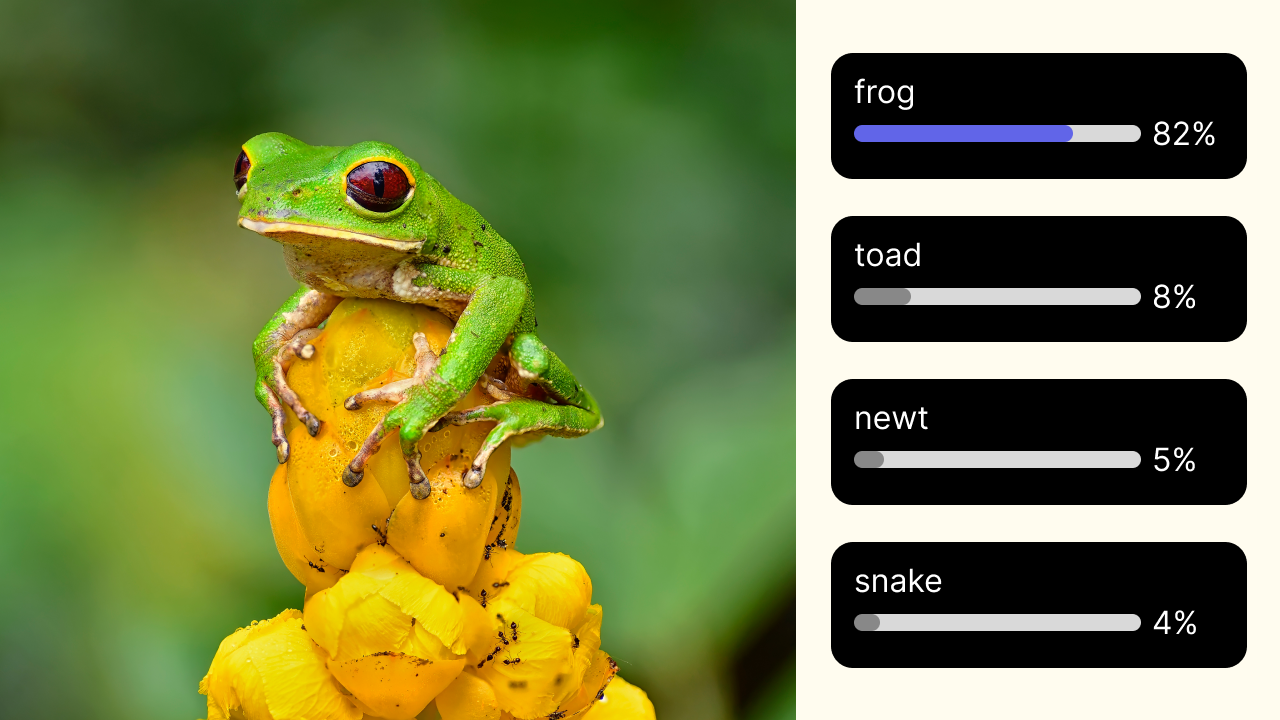
Image Classification

Employs inverted residual blocks with linear bottlenecks for highly efficient, low-latency inference.

Ideal for on-device vision tasks such as mobile apps, robotics, and embedded systems where power and compute are limited
Generative AI

Moondream2-2B

Vision-Language

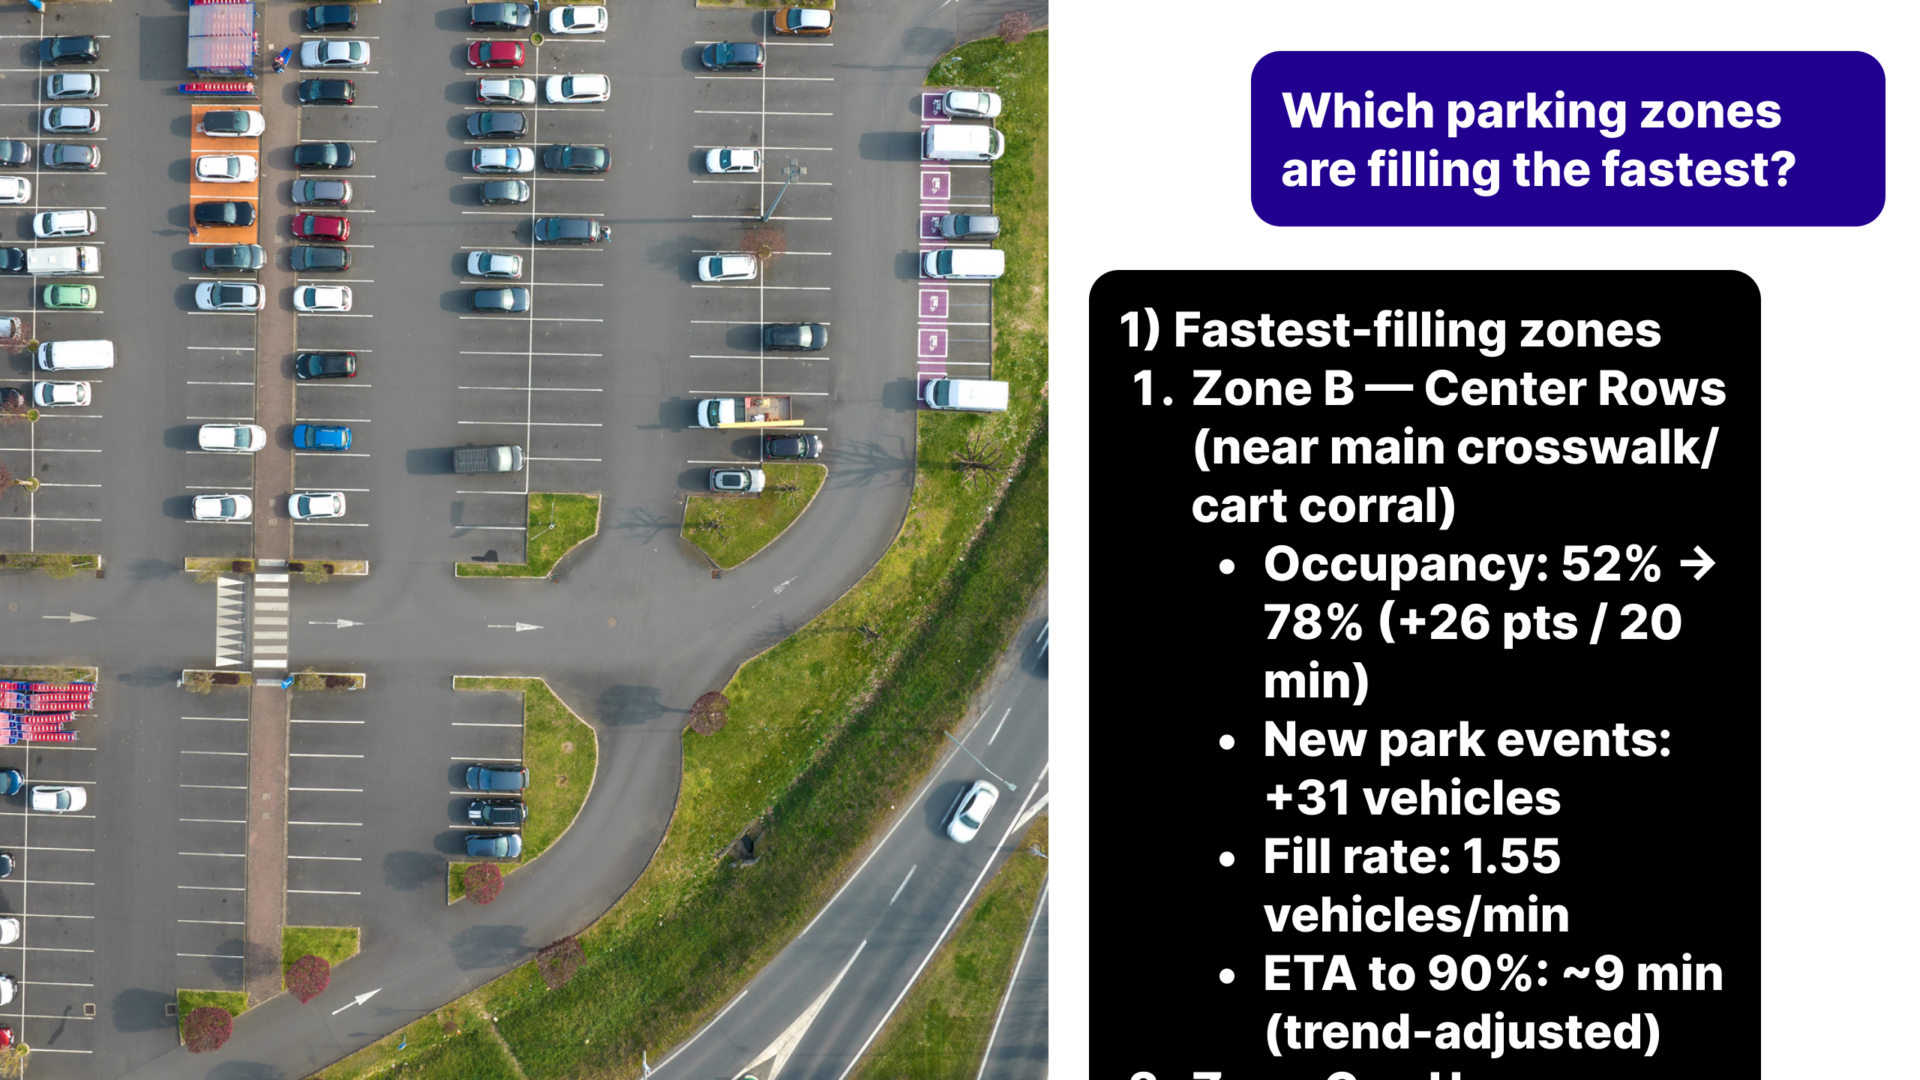
A compact ~2B-parameter vision-language model designed for efficient multimodal inference, combining a lightweight vision encoder with a language model for image understanding and text generation.
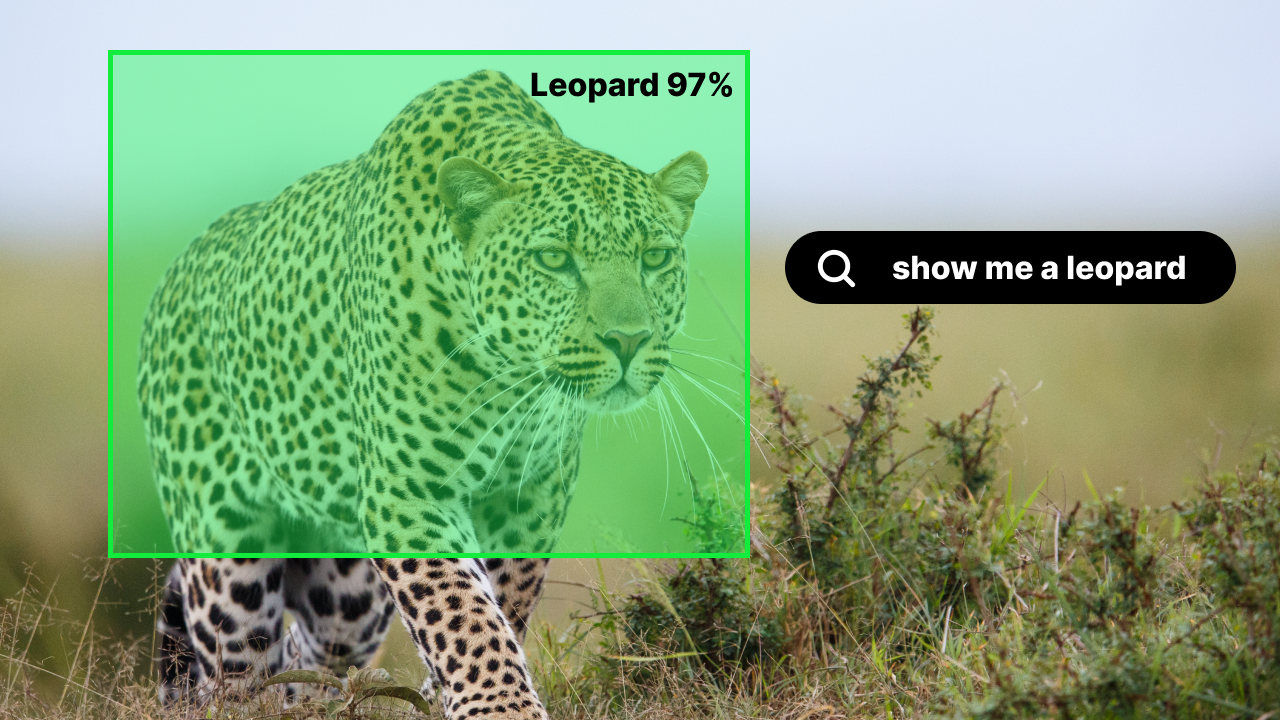
Well suited for resource-constrained edge applications such as image captioning, visual question answering, object understanding, and lightweight visual assistants.
Multimodal

OWLv1 CLIP ViT-B/32

Object Detection

OWL-ViT is a zero-shot open-vocabulary detector that aligns visual features with text embeddings from a pre-trained language model, supporting flexible object detection without task-specific training.

Ideal for open-vocabulary detection scenarios such as robotics, wildlife monitoring, and general object detection where new object categories may appear dynamically.
Computer Vision

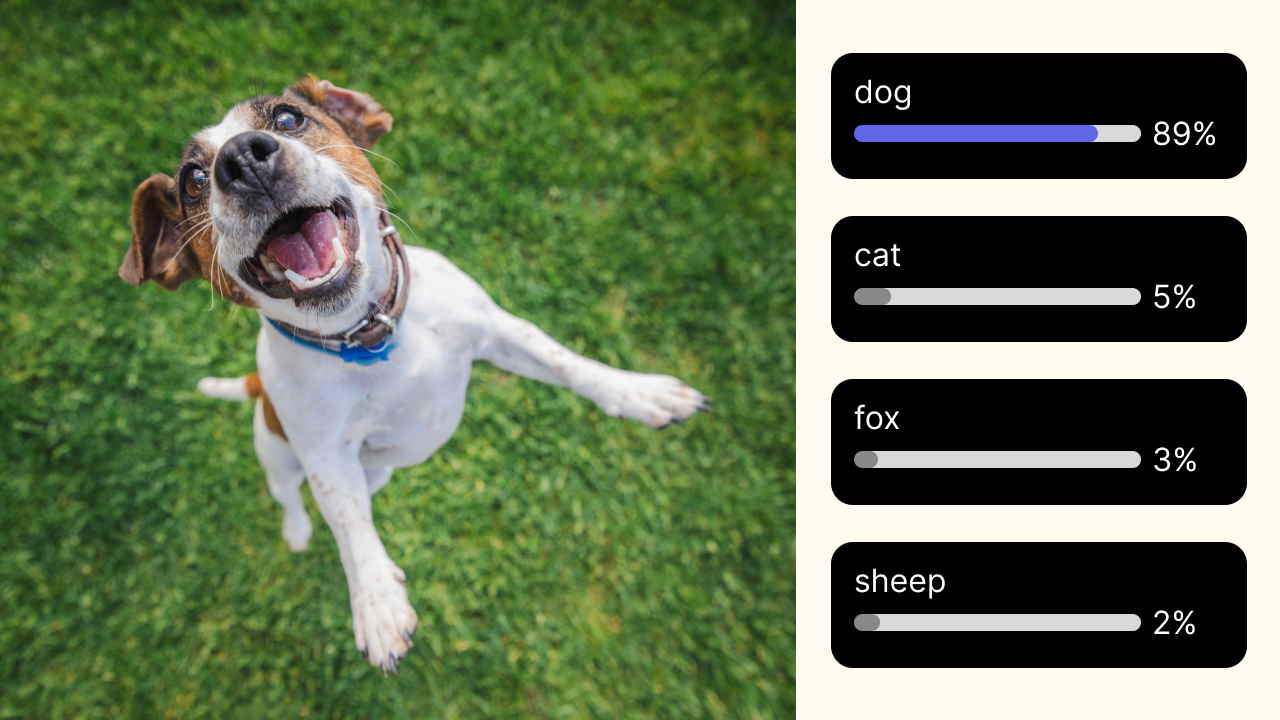
ResNet-50

Image Classification

Uses deep residual blocks that stabilize training and enable very deep CNN architectures.

Strong baseline for classification and widely used as a feature extractor in detection, segmentation, and re-ID pipelines.
Computer Vision

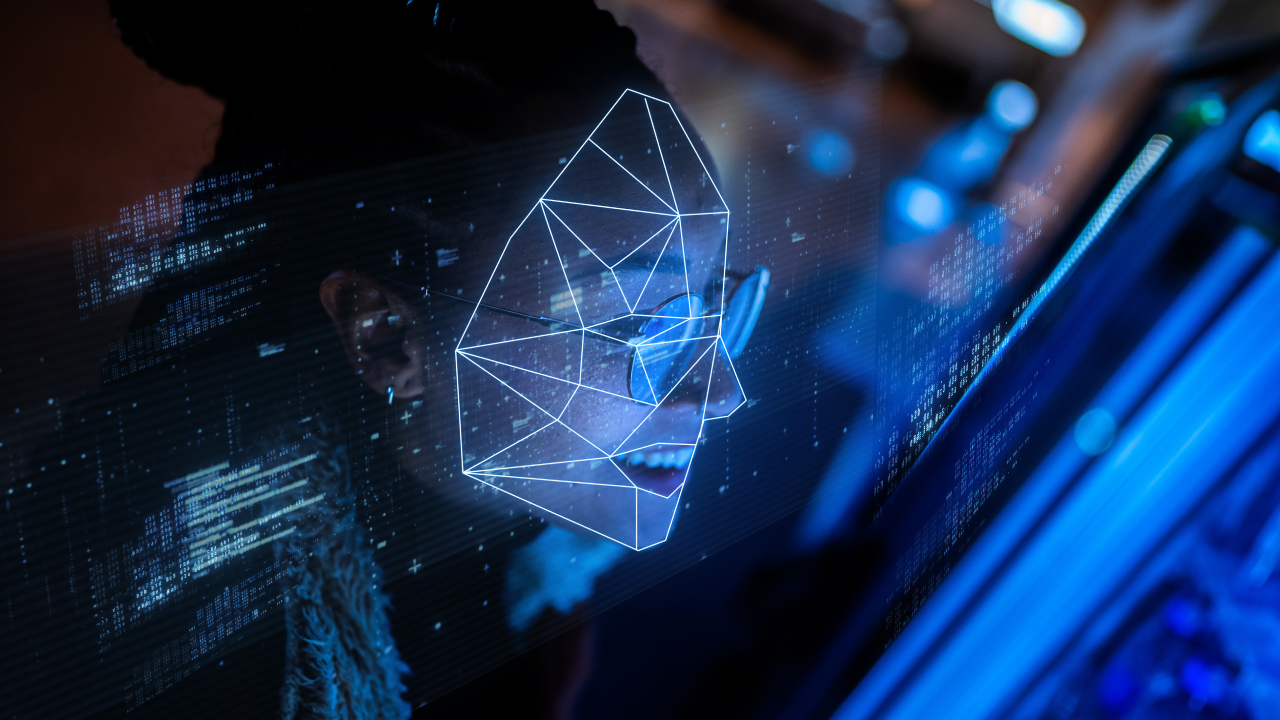
RetinaFace-ResNet50

Face Recognition & Face Detection

RetinaFace is a high-precision, single-stage face detector using a multi-task CNN to predict bounding boxes, facial landmarks, and dense feature maps for accurate detection under varying poses and occlusions.

Ideal for real-time face detection in surveillance cameras, video conferencing, and access control systems where robust detection is required
Computer Vision

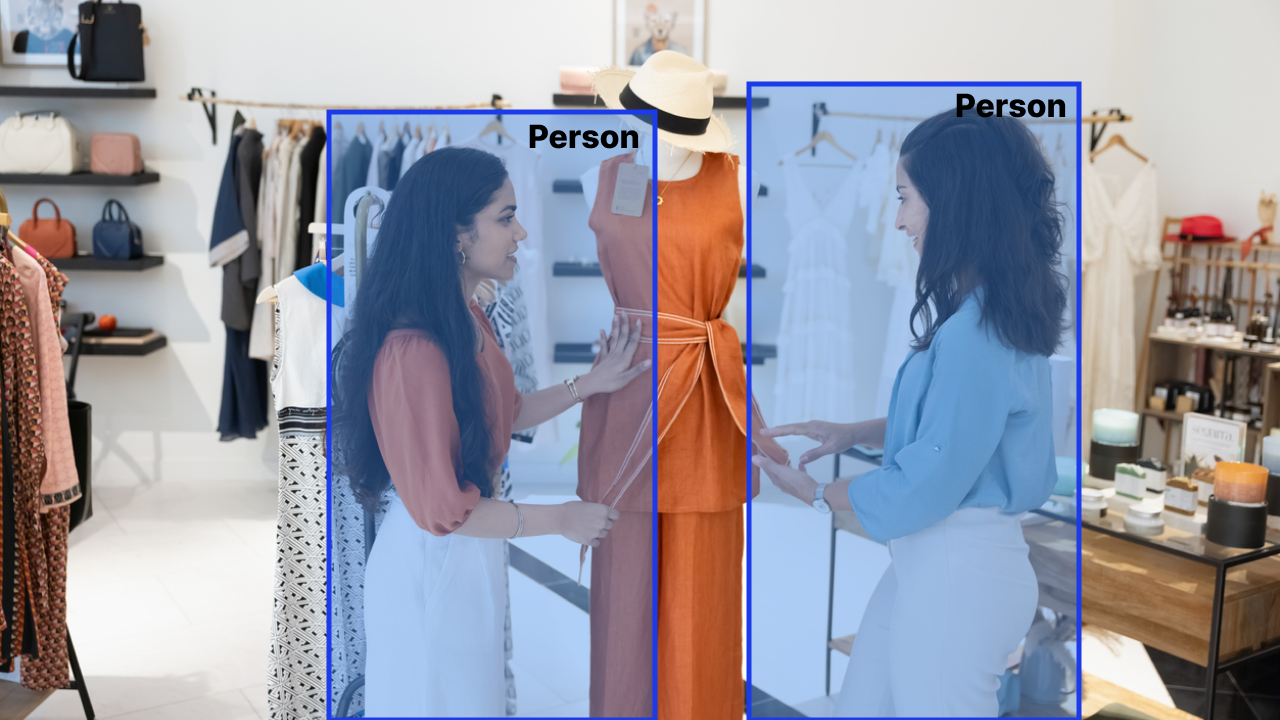
RTMDet-Nano
Object Detection
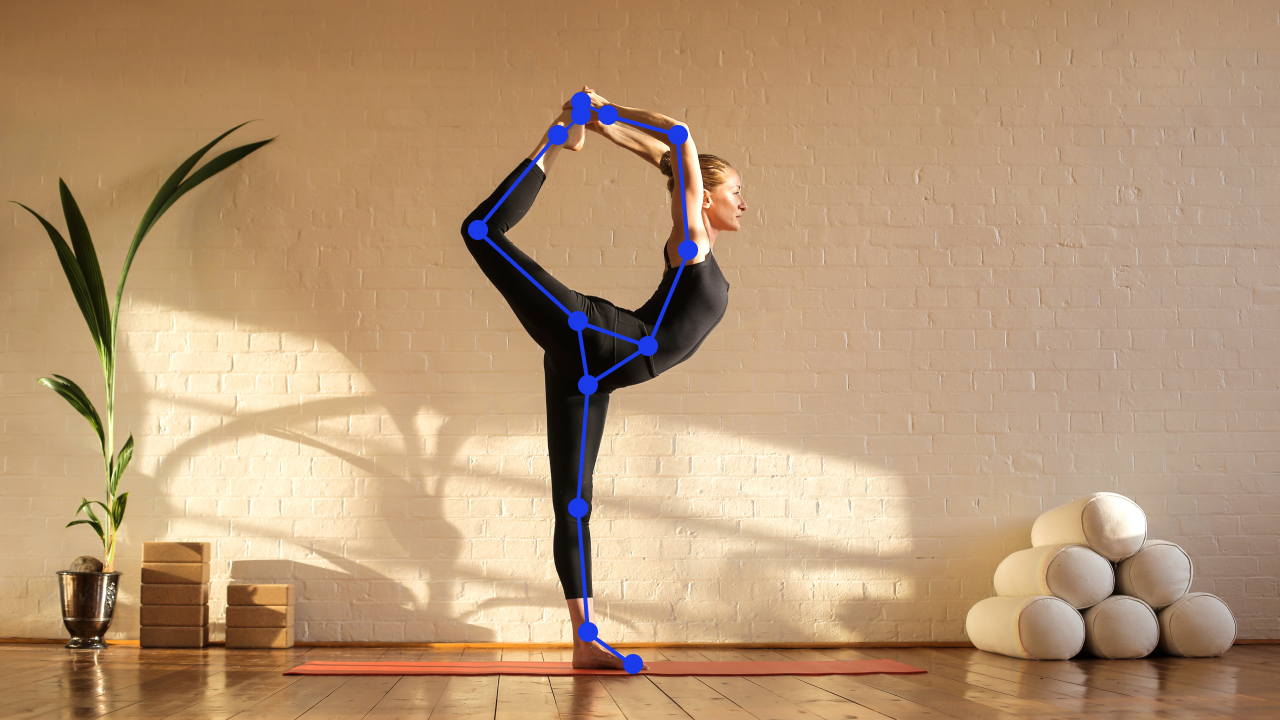
An anchor-free RTMDet object detector fine-tuned specifically for person class detection, using an efficient backbone and decoupled detection head for accurate, real-time human localization.
Designed for surveillance, smart retail analytics, crowd monitoring, pose estimation and safety systems where reliable real-time person detection is required.
Computer Vision

RTMPose-M

Pose Estimation

RTMPose is a high-speed, high-accuracy keypoint detector using an efficient CNN backbone, decoupled head, and refined training recipe for robust multi-person pose estimation.

Used for real-time human pose tracking in sports analytics, fitness apps, surveillance, driver monitoring, gesture control, and robotics.
Multimodal

SigLIP2-Base-Patch16-224
Vision-Language
SigLIP2 is a vision-language encoder based on Vision Transformers that uses a sigmoid-based image-text loss and improved training techniques to produce strong, semantically aligned image and text representations.
Well suited for zero-shot image classification, image-text retrieval, visual search, and multimodal embedding applications where efficient and accurate image-text matching is required.
Generative AI

SmolVLM2-500M

Vision-Language

A compact ~500M-parameter vision-language model combining a lightweight visual encoder with a small language backbone, optimized for low-latency multimodal understanding with minimal compute and memory footprint.
Well suited for edge AI use cases such as lightweight visual assistants, image captioning, basic visual question answering, and real-time multimodal analytics on resource-constrained devices.
Computer Vision

SuperPoint

Feature Detection
SuperPoint is a self-supervised CNN-based feature detector and descriptor network that jointly identifies interest points and generates compact descriptors for robust feature matching across images.
Well suited for visual localization, SLAM, image stitching, and camera-based navigation where reliable feature correspondences are needed under changes in viewpoint and lighting.
Computer Vision

SwinV2-Tiny

Image Classification

Introduces scaled cosine attention and improved positional encoding while keeping Swin’s hierarchical, shifted-window attention.

Excellent for large-scale or high-resolution applications such as medical imaging, remote sensing, or HD autonomous-driving inputs.
Multimodal

TinyCLIP-ViT8M16
Image Classification
TinyCLIP is a compact CLIP-based vision-language model that uses knowledge distillation to retain image-text alignment capabilities in a significantly smaller and more efficient architecture.
Well suited for edge applications such as zero-shot image classification, visual search, image-text retrieval, and lightweight content matching where low memory usage and fast inference are important.
Computer Vision

Topformer-B

Semantic Segmentation

TopFormer combines lightweight CNN backbones with transformer-based context modules to efficiently capture long-range dependencies while maintaining real-time inference speed.

Suitable for mobile and edge devices, urban scene parsing, and robotics where a balance between speed and segmentation accuracy is required
Multimodal

X-CLIP Base-Patch32-8Frames
Video-Language Understanding
X-CLIP extends CLIP to video by incorporating temporal modeling over frame-level visual features, enabling joint video-text representations for understanding video content.
 Well suited for video understanding tasks such as zero-shot action recognition, video-text retrieval, and content classification where temporal context is important.
Computer Vision

YOLO26s

Object Detection
YOLO26 is a modern, end-to-end YOLO detector from Ultralytics designed to simplify inference by eliminating traditional post-processing dependencies while delivering a strong balance of detection accuracy, latency, and computational efficiency.
Well suited for real-time edge vision applications such as autonomous driving, traffic monitoring, smart surveillance, robotics, and industrial inspection where low latency and efficient deployment are important.
Computer Vision

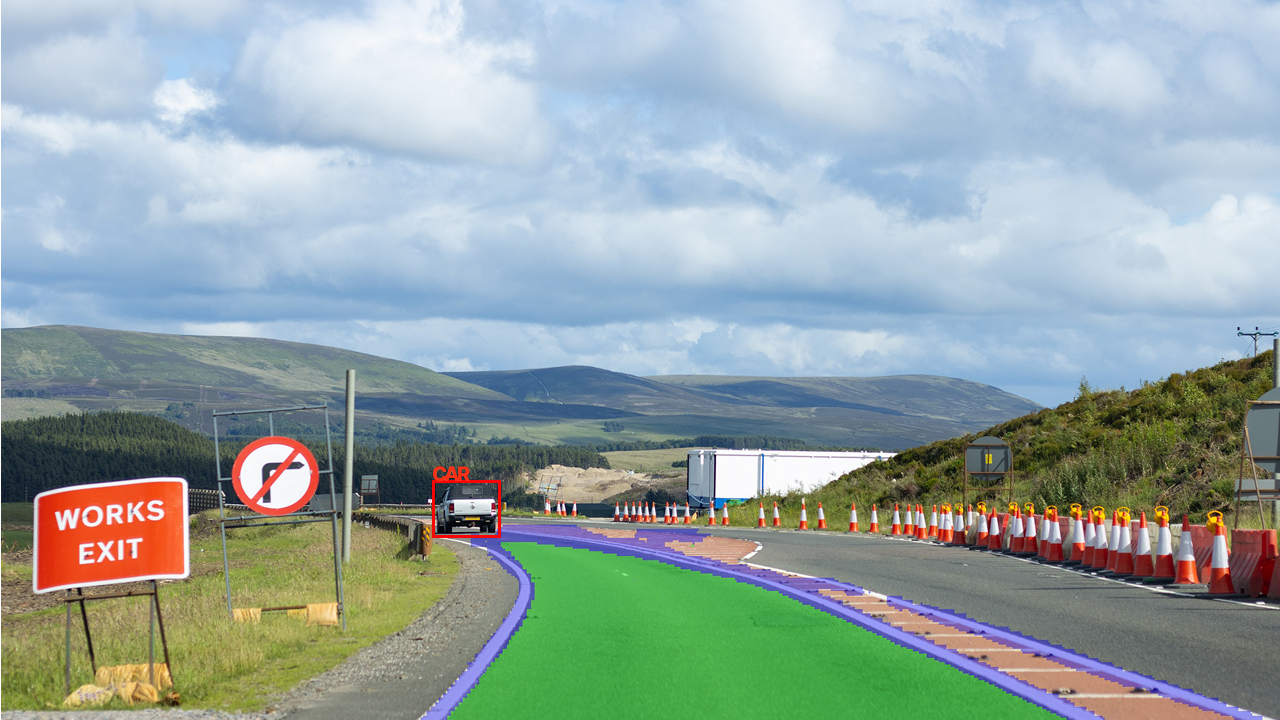
YOLOP

Multi-Task    Object Detection
YOLOP is a real-time multi-task perception network that jointly performs object detection, drivable-area segmentation, and lane detection using a shared backbone for efficient inference.
Designed primarily for ADAS feature, enabling simultaneous detection of vehicles/pedestrians, identification of drivable regions, and lane-boundary detection from camera input.
Computer Vision

YOLOv8s

Object Detection
YOLOv8 is a modern, anchor-free YOLO architecture from Ultralytics with a streamlined backbone and decoupled detection head, designed to deliver a strong balance of accuracy, speed, and computational efficiency.
Well suited for real-time edge vision applications such as vehicle and pedestrian detection, smart surveillance, traffic monitoring, and industrial inspection.
Computer Vision

YOLOX-S

Image Classification

YOLOX_s is machine learning model performing object detection on COCO dataset.

YOLOX modernizes the YOLO pipeline with an anchor-free design, decoupled head, strong data augmentation, and SimOTA label assignment.

Ideal for real-time, on-device applications such as traffic monitoring, dashcams, drones, and pedestrian detection where speed and robustness under variable lighting are critical.

CLOSE